Assess workplace competence through realistic AI role-play.
Learners work through realistic workplace scenarios with AI agents. Responses are scored against your rubrics with criterion-level feedback, and assessors review, moderate and can override every result. Built for VET, pharmaceutical quality and enterprise training.
From scenario to evidence, in four steps.
Author
Create scenario-based assessments mapped to your units of competency or training standards, with approval workflows and versioning.
Role-play
Learners converse with AI agents playing customers, colleagues or staff in realistic scenarios, gathering what they need to complete the task.
Score
Rubric-based scoring with explainable feedback: every mark comes with its reasoning, traceable to a criterion.
Review and report
Assessors review, moderate and override results, with reporting for validation, moderation and compliance reviews.
Agents that stay in character.
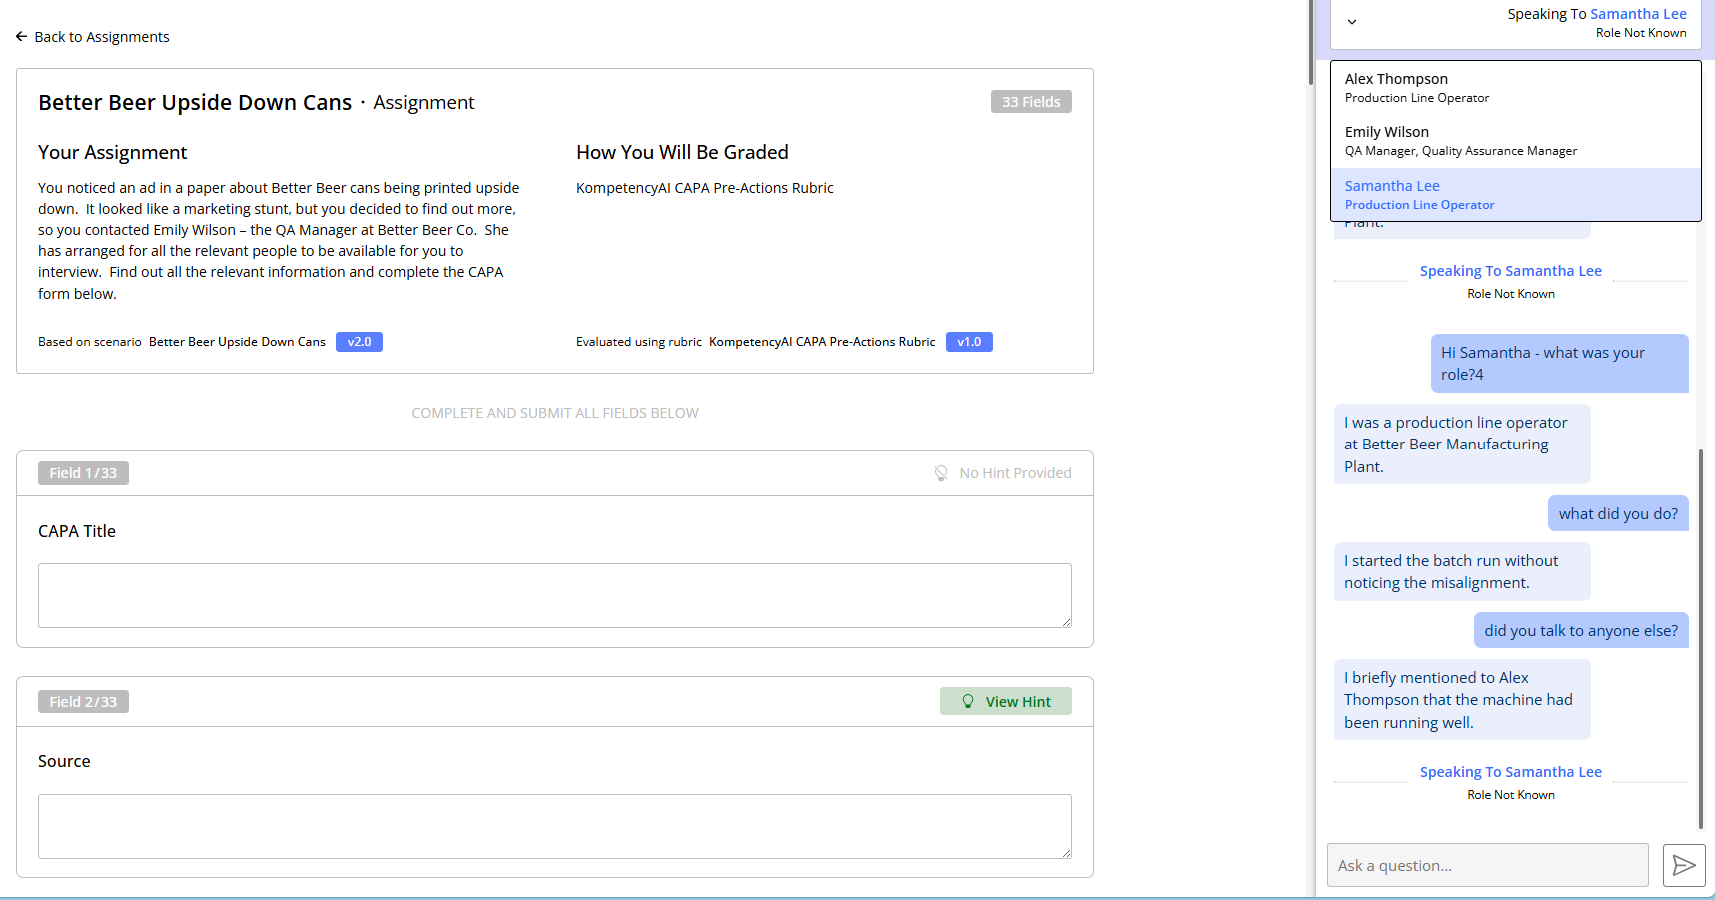
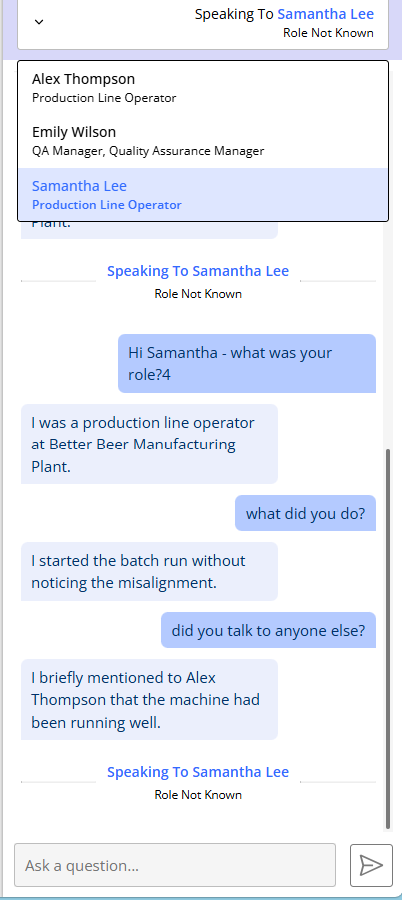
Learners practise the conversations their job requires: a quality investigation, a difficult customer, a compliance interview. Agents play the people in the scenario, respond to what the learner asks, and keep the exchange within the bounds you authored.
- Several characters per scenario, each with a defined role and knowledge
- Learners choose who to speak to and gather evidence through questioning
- The conversation is kept as part of the assessment record
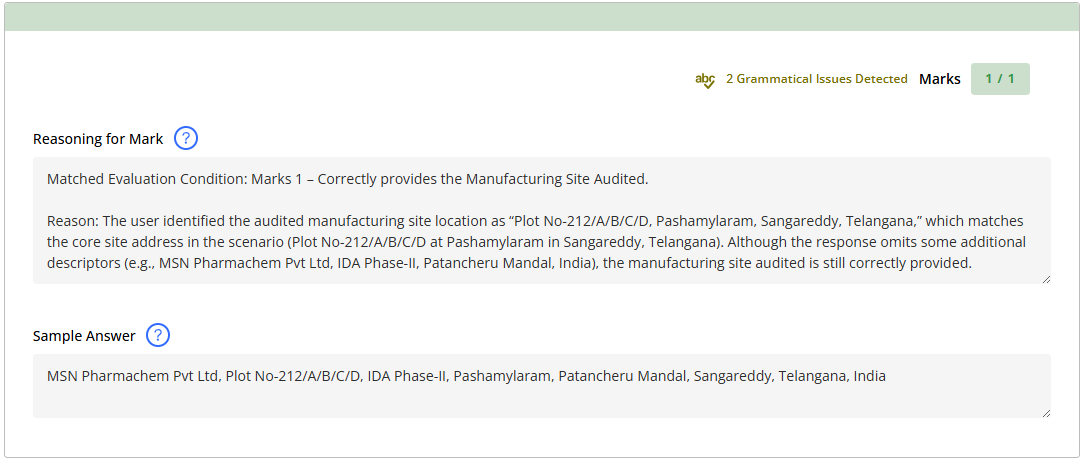
Scoring your validators can stand behind.
Every score is mapped to your rubric and explained criterion by criterion, with the reasoning and a sample answer beside the learner's response. Assessors start from a scored draft rather than a blank rubric, and remain responsible for the result.
- Criterion-level reasoning for every mark
- Assessor review, moderation and override at every stage
- An evidence trail for Vocational Education and Training (VET) audits
Scenarios your team writes, approves and versions.
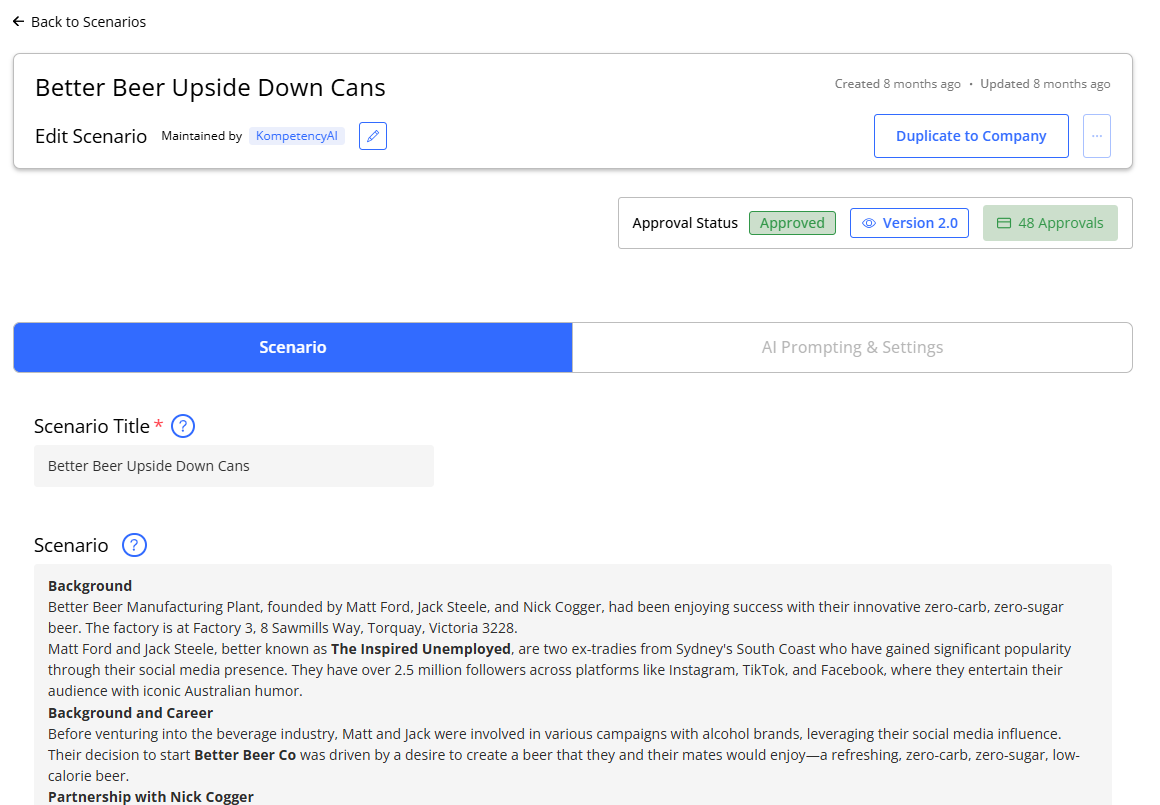
Scenarios are authored in plain language: the background, the people involved and what the learner must find out. Approval workflows mean no single person can publish an assessment alone, and each version is recorded.
- Approval status and version history on every scenario
- Scenarios can be duplicated and adapted for your organisation
- Separate settings for the scenario content and the AI prompting
Built for regulated training environments.
KompetencyAI runs on XponixAI's sitewide security posture: dedicated infrastructure on Azure OpenAI or AWS Bedrock, AES-256 encryption, SAML SSO, and a written guarantee that learner data is never used to train AI models. Australian data residency available.
See a role-play assessment run end to end.
We walk through a scenario, the rubric scoring and the assessor review tools, and answer your questions.
Request a KompetencyAI demo